AI Model Fine-Tuning & Sovereign LLM Adaptation
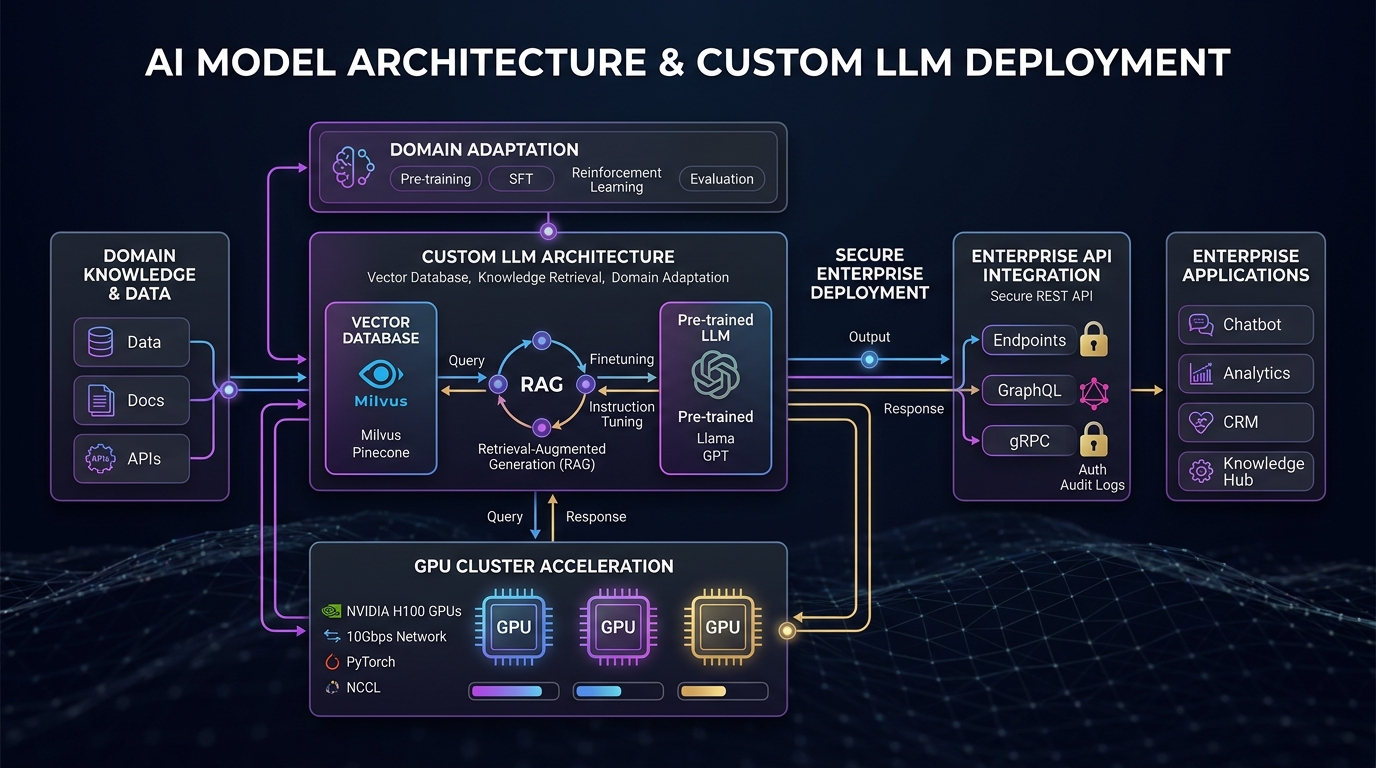
Transform open-weight foundational models (Llama 3, Mistral, DeepSeek) into proprietary, high-precision intelligence engines trained strictly on your enterprise domain data. Engineered with zero third-party data leakage and complete VPC sovereignty.
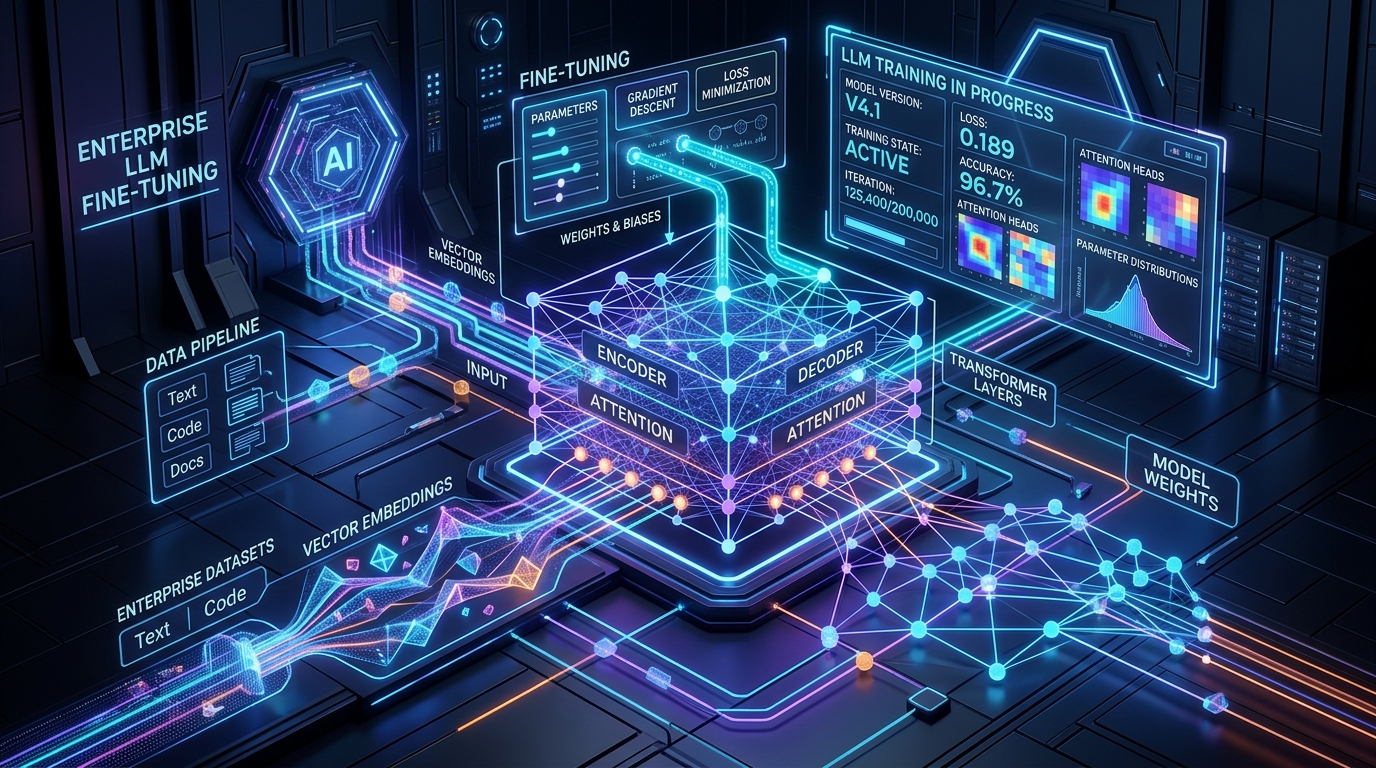
Enterprise Intelligence Built on Your Terms
Standard generic APIs leak sensitive prompts and suffer from hallucinations. Our fine-tuning pipeline embeds deep organizational knowledge into the model's neural weights.
Domain Vocabulary & Strict Compliance
We align foundational models with industry-specific lexicons (Legal, Medical EHR, Banking, Energy), enforcing deterministic JSON outputs and adherence to local regulatory constraints.
Parameter-Efficient LoRA / QLoRA
Leverage cutting-edge Low-Rank Adaptation (LoRA) and 4-bit Quantization (QLoRA) to fine-tune billion-parameter models at a fraction of standard compute costs with rapid iteration cycles.
Zero Data Leakage Sovereign VPC
Deploy trained weights inside your isolated private AWS / GCP / Azure tenant or on-premise NVIDIA GPU clusters. Your proprietary data never touches shared public APIs.
Hybrid RAG + Weight Integration
Combine parametric memory (fine-tuned weights) with dynamic vector databases (Milvus, Qdrant, Pinecone) for real-time live retrieval with near-zero hallucinations.
vLLM High-Throughput Serving
Production inference engines optimized with PagedAttention and vLLM continuous batching, serving hundreds of concurrent requests at ultra-low millisecond latency.
DPO & Enterprise Guardrails
Direct Preference Optimization (DPO) and NeMo guardrails to eradicate jailbreaks, enforce brand tone, and guarantee toxic-free outputs across all user touchpoints.
Generic Public Models vs. Techline Fine-Tuned Models
Why top enterprises transition from generic consumer chatbots to private fine-tuned intelligence.
| Evaluation Dimension | Generic LLMs (Prompting) | RAG Only | Fine-Tuned Enterprise Model ⭐ |
|---|---|---|---|
| Domain Knowledge & Tone | Generic / Inconsistent | Contextual search only | Native domain vocabulary & style |
| Prompt Token Costs | High (long repetitive context) | Moderate (chunk embeddings) | Lowest (knowledge baked into weights) |
| Inference Latency | High (large prompt processing) | Moderate (+ vector search step) | Ultra-fast (concise prompts, vLLM) |
| Data Sovereignty & Privacy | Third-party cloud exposure | Depends on vector DB | 100% Private VPC / On-Premise GPU |
| Structured JSON & Tool Calling | Frequent formatting errors | Variable consistency | 99.8% Deterministic JSON & API calls |
How We Fine-Tune & Deploy Custom Models
Our rigorous engineering workflow ensures your model achieves high benchmark performance, reduced latency, and cost-effective scalability.
Data Audit, Curation & Tokenization
Extraction, de-duplication, PII redaction, instruction pair formatting, and synthetic data generation from your enterprise knowledge sources.
Base Model Selection & Parameter Optimization
Benchmarking candidate architectures (7B to 70B+ parameters) and configuring hyper-parameters, learning rate schedules, and LoRA rank matrices.
Supervised Fine-Tuning & Evaluation Benchmark
Distributed multi-GPU training with validation against automated test suites, perplexity metrics, and human-in-the-loop domain scoring.
Quantization, High-Throughput Serving & API Integration
Model quantization (AWQ/GPTQ/GGUF), continuous batching inference deployment with vLLM, and seamless REST/gRPC API integration.